

AI Code Review for Security: A Practical Guide for Dev Teams
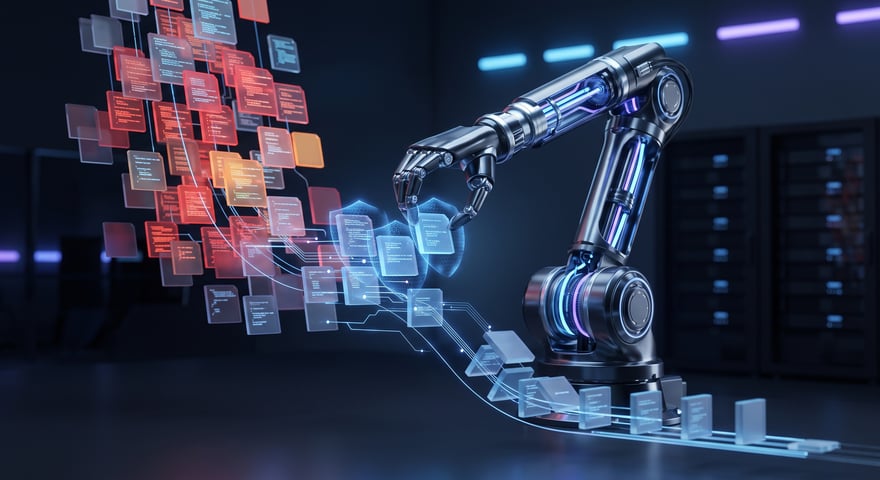
Most AI code review tools were built to make code better, not safer. They catch style issues, suggest refactors, and flag obvious bugs. Security is usually an afterthought, if it's addressed at all. That leaves a real gap for dev teams who need something more specific: a way to catch vulnerabilities before they ship, without drowning developers in noise.
This guide walks through how security-focused AI code review actually works, where it falls short of manual review, and what to look for if you're adding it to your pull request workflow.
Quick answers up front: AI code review catches vulnerabilities that linters miss by tracing how data moves across functions and files, and by reasoning about business logic instead of just matching known-bad patterns. It's not a replacement for manual security review, but it does cut down the volume of issues that actually need a human's attention. And you can add it to your existing PR workflow by connecting a tool to your source control platform's pull request events, so findings show up as comments right on the diff.
Why do general AI code review tools miss security vulnerabilities?
Most general-purpose AI code review tools are optimized for code quality: consistency, bug detection, test coverage, that kind of thing. Security tends to sit low on the priority list. Tools built specifically for security, like Amplify Security, are trained and tuned around a different goal: finding real vulnerabilities and doing it without burying developers in false alarms.
The gap comes down to a few things these tools weren't designed to do:
- Pattern matching instead of data flow analysis. A general tool can flag something like eval() being used, but it won't trace a user-controlled input as it moves through three service layers before landing in that eval() call unsanitized.
- Single-file scope instead of cross-file context. Plenty of tools review one file at a time. Real vulnerabilities often span several: a controller that accepts input, a service that processes it, and a data layer that executes it.
- Style-weighted noise. When a tool flags a missing docstring right next to a SQL injection risk, developers stop trusting either finding. Low-severity noise buries the stuff that actually matters.
- No path to a fix. Getting a note that says "potential XSS" with no explanation of the injection path or a concrete fix creates extra work without actually reducing risk.
Bolting a separate SAST scanner on top doesn't solve this either. Now developers are checking two different tools in two different places, with a lot of overlap and no shared sense of what to fix first.
How does AI code review catch security vulnerabilities that linters miss?
Linters and traditional SAST tools work off abstract syntax trees and predefined rule sets. They're good at catching known patterns: hardcoded credentials, deprecated crypto functions, obvious injection points. Where they fall short is anything that requires actual reasoning about what the code is doing, and it's part of why reducing SAST false positives has become its own discipline.
Security-focused AI code review adds a few capabilities on top of that.
Contextual data flow analysis
Instead of just asking "is this function dangerous," AI models can trace how data actually moves through an application. That means catching things like:
- User input that reaches a database query after passing through a sanitization function that doesn't cover the specific injection vector being used
- Authorization checks that exist, but get applied inconsistently across different endpoints
- Secrets that pass between services in a way that ends up exposing them in logs
Business logic flaw detection
Linters have no concept of intent. AI models can infer intent from how code is structured and named, which lets them catch things like:
- A payment flow that quietly allows negative quantities
- A rate limiter that checks by session but not by IP, so it's bypassed the moment someone logs out and back in
- An access control check that confirms a user's role but never checks whether they actually own the resource (a classic IDOR)
These are exactly the kinds of issues that slip through every linting pass and only get caught later, usually in a penetration test.
Understanding framework-specific security patterns
Modern apps lean on frameworks that come with their own security models: Django's ORM escaping, Rails' strong parameters, Spring Security's filter chains. AI models trained on security-specific data can tell whether those built-in protections are being used correctly, worked around, or misconfigured. This kind of cross-file tracing is closely related to reachability analysis, which asks a similar question at the dependency level: is this vulnerable code path actually exploitable, or just theoretically present.
|
Capability |
Linter / SAST |
General AI Review |
Security-specific AI review |
|
Hardcoded secrets |
Yes |
Yes |
Yes |
|
Known dangerous functions |
Yes |
Yes |
Yes |
|
Cross-file data flow |
Limited |
Limited |
Yes |
|
Business logic flaws |
No |
Rare |
Yes |
|
Framework misuse |
Rule-dependent |
Partial |
Yes |
|
Remediation guidance |
Generic |
Generic |
Context-specific |
|
Noise level |
High |
Medium-high |
Low (when tuned for security) |
Is AI code review reliable enough to replace manual security review?
No, and it's worth being upfront about that.
AI code review works best as a force multiplier for security teams, not a stand-in for them. Here's a realistic breakdown of what it handles well and where a human still needs to be in the loop.
What AI handles well:
- Known vulnerability classes at scale. Injection, XSS, SSRF, path traversal, insecure deserialization. AI catches these consistently across large codebases in a way manual review just can't match for speed.
- Consistency. It applies the same level of scrutiny to every single PR, no matter how tired the reviewer would've been by Friday afternoon.
- Speed. Findings show up in minutes instead of sitting in a security team's review queue for days or weeks.
Where humans are still required:
- Novel attack vectors. AI models reason from what they've been trained on. A genuinely new class of vulnerability, or an attack chain unique to your application, might not match anything the model has seen before.
- Architectural security decisions. Whether to use a service mesh for mTLS, how to design token rotation, where to draw trust boundaries. These require human judgment about threat models and business context that a code review tool isn't positioned to make.
- Verification of critical findings. For anything high-severity, a person should confirm the finding, assess how exploitable it really is, and validate that the fix actually works.
The practical model most teams land on:
- AI reviews every PR, catching the well-understood vulnerability classes and giving remediation guidance right in the diff.
- Security engineers review whatever AI escalates, focusing on high-severity or low-confidence findings.
- Manual deep review stays reserved for critical paths: authentication, authorization, payments, data handling.
That tiered setup lets a small security team cover a much larger engineering org without becoming the bottleneck everyone routes around. It's essentially the same logic behind automating vulnerability triage without losing the context that tells you which findings actually deserve attention.
How do I add AI-powered security code review to my existing pull request workflow?
Where the findings show up matters more than people expect. Security findings that live outside a developer's normal workflow get ignored. Findings that show up inline, on the PR diff, right when the developer is already thinking about that code, actually get fixed. That's the same principle behind automating vulnerability remediation directly in GitHub pull requests.
What to look for in an integration:
- SCM-native PR comments. Findings should appear as review comments on specific lines in GitHub, GitLab, Bitbucket, or Azure DevOps, not tucked away in a separate dashboard nobody checks.
- Diff-scoped analysis. The tool should understand the broader codebase, but only surface findings relevant to what actually changed in the PR. A full-repo scan dumped into every PR just creates noise.
- Actionable remediation. Each finding should show the vulnerable code path, explain why it's exploitable, and offer a concrete fix, ideally as a suggested change the developer can commit directly. This is the core idea behind auto remediation: letting AI generate the fix, not just flag the problem.
- Configurable severity thresholds. Teams need the ability to decide which severities block a merge and which are just advisory, which only works if findings are prioritized on more than CVSS alone.
- A low false-positive rate. This is the single biggest factor in whether a tool sticks around. Developers turn off anything that cries wolf too often. Tools tuned for precision over recall are the ones that earn trust.
Typical rollout steps:
- Install the app or webhook in your SCM (a GitHub App, GitLab webhook, or similar).
- Grant repository access. Some tools need full-repo access for cross-file analysis; others work fine on just the diff.
- Set policy: decide which findings block merges (critical, high) and which are comment-only (medium, low).
- Tune over time. Suppress or adjust anything that's producing false positives in your specific codebase.
- Monitor adoption. Track how many findings developers actually resolve versus dismiss. A high dismiss rate is a sign of noise. A high resolve rate is a sign the tool is earning its keep.
What about your existing SAST and SCA tools?
AI security code review doesn't necessarily replace what you already have running. It sits in a different spot:
- SAST runs full scans, usually in CI, producing comprehensive reports that matter for compliance and baseline coverage.
- SCA flags vulnerable dependencies, which is a separate problem from code review entirely.
- AI security code review focuses on the delta, meaning what changed in this specific PR, and reasons about it in context. It's the fastest feedback loop of the three.
The strongest setup runs all three together, with AI code review acting as the first line of defense that catches issues before they even reach the CI scan.
What makes security-specific AI code review different from bolting security rules onto a general tool?
The difference comes down to training, depth of analysis, and quality of output.
A general AI code review tool with a few security rules added on is basically a linter wearing a language model as a costume. It matches patterns and generates explanations, but it's not reasoning from a security-first foundation. This is also where governance starts to matter: as more AI-generated findings and fixes flow through a codebase, teams need to think about closing the governance blind spot at enterprise scale, not just the accuracy of any single finding. A tool actually built for security does a few things differently:
- It prioritizes security signal. The model is trained or fine-tuned on vulnerability databases, security advisories, and exploit patterns, not just general open-source code.
- It minimizes noise on purpose. Every finding that turns out not to be a real vulnerability chips away at developer trust, so security-specific tools optimize hard for precision.
- It provides exploit-aware context. Instead of "this might be an injection," it explains something like: user input from a request parameter reaches a database execution call on a specific line without parameterization, and an attacker could use that to inject arbitrary SQL.
- It ties findings to an actual fix. Not "sanitize your input" but the specific line-level change that closes the hole.
Frequently asked questions
Does AI code review replace a security engineer? No. It's better thought of as a filter that clears out the well-understood, high-volume vulnerability classes so security engineers can spend their time on novel attack vectors, architectural decisions, and verifying the highest-severity findings.
Will AI code review slow down my PR pipeline? It shouldn't, if it's built right. Findings should post within minutes and scope themselves to what actually changed in the diff, not a full-repo scan on every commit. If a tool takes longer than a few minutes to respond, it's going to get in the way of how developers actually work.
Can AI code review work alongside our existing SAST and SCA tools? Yes. They cover different ground. SAST gives you comprehensive, compliance-friendly scans. SCA flags risky dependencies. AI code review focuses on what changed in the current PR and reasons about it in context, making it the fastest of the three to give feedback.
How do we know if the tool is actually working once we've adopted it? Track two numbers: how many findings are true positives, and how many developers act on findings without being told to. If both are trending up and your security team's review backlog is shrinking, it's working. If not, it's either misconfigured for your codebase or not the right fit.
What's the biggest reason teams abandon an AI code review tool? False positives. If a tool cries wolf too often, developers stop reading its comments entirely, and it becomes background noise instead of a safeguard. Precision matters more than catching every possible issue.
Getting started
Security-specific AI code review isn't a silver bullet, and no serious vendor should tell you it is. What it does well is catch well-understood vulnerability classes at the speed your team is already shipping code, freeing up your security engineers for the harder problems that still need a human brain.
Start small. Pick a couple of high-risk repositories, the ones touching authentication, payments, or user data, and run a tool against them for a couple of weeks. Watch how many findings are true positives, how many developers act on without being asked, and whether your security team's review load actually goes down. If those numbers move the right way, expand from there, the same way teams scale custom detection agents once the first rollout proves itself out.
Amplify Security is built around this exact model: security-first analysis wired into the workflows developers already use, low-noise findings, and remediation that points to a real fix instead of a generic warning. If you want to see how it fits into your pipeline, request access to Amplify Console and get a walkthrough of the platform, or head to amplify.security to explore what the harness covers end to end.
Subscribe to Amplify Weekly Blog Roundup
Subscribe Here!
See What Experts Are Saying
BOOK A DEMO
Jeremiah Grossman
Founder | Investor | Advisor
Saeed Abu-Nimeh
CEO and Founder @ SecLytics
Kathy Wang
CISO | Investor | Advisor

Alex Lanstein
Chief Evangelist @ StrikeReadyFrequently
Asked Questions
What is vulnerability management, and why is it important?
Why is vulnerability management important?
What makes vulnerability management extremely challenging in today’s high-growth environment?
How can Amplify help me with vulnerability management?
What technology does the Amplify platform integrate with?
Have a
Questions?
Contact Us
Ready to
Get started?
Book A GUIDED DEMO
