

How to Deploy Custom Detection Agents at Scale Across Your Codebase
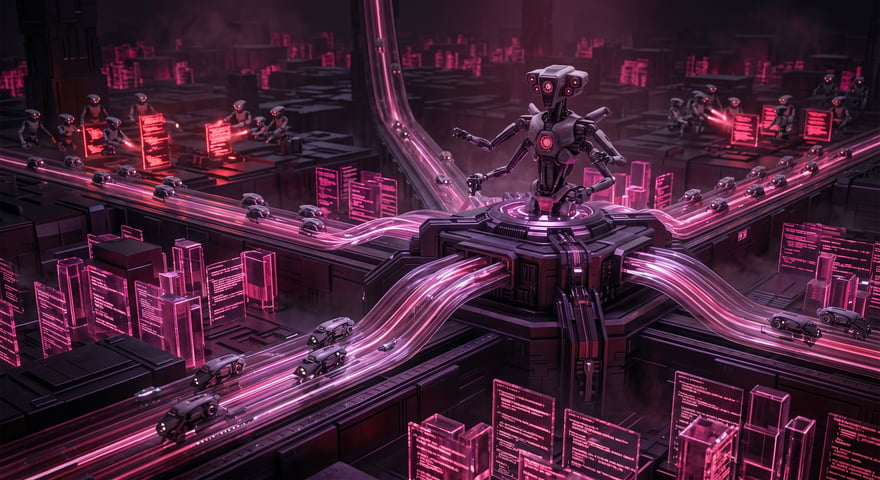
A detection agent in application security is an autonomous, configurable unit of analysis that evaluates code against a specific vulnerability pattern or security policy and returns structured findings. To scale custom vulnerability detection across many repositories, you deploy these agents as modular, language-aware components that run in CI/CD pipelines, share a centralized rule configuration, and pair every detection with remediation guidance. AI-powered agents detect specific vulnerability patterns at scale by combining static analysis primitives with LLM-based reasoning, so teams can encode domain-specific knowledge without writing individual regex rules for each repository. This is the architecture pattern behind Amplify Security's code review engine.
What is a detection agent in application security?
A detection agent is a discrete, self-contained analysis component responsible for one job: evaluate a code change against a defined vulnerability pattern and produce a finding with enough context for a developer to act on it.
Detection agents differ from monolithic SAST scanners in several ways:
- Scoped responsibility. Each agent targets a specific class of vulnerability (for example, SQL injection via string concatenation, insecure deserialization in a particular framework, or hardcoded secrets matching a defined entropy threshold).
- Independent execution. Agents run in parallel. Adding a new agent does not require modifying or redeploying existing ones.
- Structured output. Each agent returns a finding object that includes the location, severity, explanation, and a suggested remediation path.
- Configurability. Teams can tune thresholds, allowlists, and pattern definitions per agent without touching the core engine.
This modular design makes agent-based detection scalable. You are not maintaining a single, growing rule file. You are managing a fleet of focused components. Amplify Security uses this agent model to provide actionable findings inline during code review.
Why do hand-written detection rules break down at scale?
Security teams that rely on hand-written SAST rules or custom semgrep/CodeQL queries across large, polyglot codebases hit predictable walls:
|
Problem |
Root Cause |
|
False positive explosion |
Rules written for one framework trigger on structurally similar but safe patterns in another |
|
Language coverage gaps |
Each language requires its own AST parser, query syntax, and maintenance burden |
|
Rule drift |
Rules written for an older version of a framework silently stop matching after dependency upgrades |
|
No remediation path |
Detection-only rules create triage backlogs with no actionable fix guidance |
|
Engineering overhead |
Dedicated AppSec engineers spend cycles writing and debugging rules instead of threat modeling |
The core issue is that hand-written rules are brittle. They encode pattern-matching logic at the syntax level without understanding the semantic intent of the code. When your codebase spans Python, TypeScript, Go, Java, and Kotlin across hundreds of repositories, the maintenance cost of syntax-level rules grows faster than the security team.
How do you architect detection agents for multi-repo, polyglot environments?
A working architecture for scale has four layers.
Layer 1: pipeline integration
Detection agents must run where code changes happen, such as pull requests, merge requests, or commit hooks. This means:
- Agents execute inside CI/CD (GitHub Actions, GitLab CI, Jenkins, etc.) as a step triggered on code change events.
- Execution is scoped to the diff, not the entire repository, to keep runtime bounded.
- Results are posted inline as PR comments or review annotations so developers see findings in context.
Layer 2: language-aware parsing
Each agent needs access to a parsed representation of the code, not raw text. This layer provides:
- Abstract syntax tree (AST) generation per language.
- Dataflow analysis where available, tracking how user input flows through function calls to sinks.
- Framework-specific context, for example recognizing that a Django @csrf_exempt decorator changes the security posture of a view.
AI agents augment this layer using LLM-based reasoning to interpret patterns that resist static encoding, such as unusual sanitization wrappers, custom middleware chains, or project-specific security conventions.
Layer 3: agent orchestration
An orchestration layer manages which agents run against which files:
- File-type routing. A .py file triggers Python-relevant agents; a .tsx file triggers React/TypeScript agents.
- Policy mapping. Organization-level policies determine which agents are active. A fintech team might enable PCI-DSS-specific agents that a SaaS platform team does not need.
- Parallelism. Agents execute concurrently with bounded resource allocation per agent to prevent one slow agent from blocking the pipeline.
- Deduplication. When multiple agents flag the same line for overlapping reasons, the orchestrator merges findings.
Layer 4: centralized configuration and tuning
Scaling detection means scaling configuration management:
- Agent definitions (what to detect, severity, remediation template) live in a central registry.
- Teams can override global settings per repository or per team via configuration-as-code files.
- Tuning feedback (marking a finding as false positive) propagates back to the agent configuration so the same false positive does not recur across repositories.
Can AI agents be customized to detect specific vulnerability patterns?
Yes. The customization surface for AI-powered detection agents operates at multiple levels.
Pattern-level customization
You define the vulnerability pattern the agent should detect. This can be:
- A known CWE category (for example, CWE-89 for SQL injection).
- A project-specific anti-pattern (for example, "any direct call to raw_query() outside the data_access module").
- A compliance requirement (for example, "all API endpoints must validate JWT expiration").
AI agents accept these definitions in natural language or structured policy format and apply them with static analysis and LLM-based reasoning. Instead of writing a regex or tree-sitter query, you describe the intent of the rule and the agent generalizes across syntactic variations.
Severity and threshold customization
Not every finding warrants the same response:
- Configure severity levels per pattern (critical, high, medium, informational).
- Set confidence thresholds below which findings are suppressed or flagged for manual review.
- Define escalation rules, for example critical findings in authentication modules block the PR, while medium findings in test files are informational only.
Remediation customization
Detection without remediation creates backlogs. Customizable agents pair each detection with:
- A remediation suggestion tailored to the specific language and framework in use.
- Code-level fix suggestions that a developer can apply directly.
- Links to internal security documentation or approved patterns.
This is a key architectural decision. The agent is both a detector and a remediator. Amplify Security's implementation pairs every detection with language-specific fix suggestions.
How do you reduce false positives without reducing coverage?
False positives are the primary reason security tooling gets disabled. At scale, even a 5% false positive rate across thousands of daily findings becomes unmanageable. The agent architecture addresses this through several mechanisms:
- Context-aware analysis. AI agents consider surrounding code context, such as function signatures, import statements, and middleware chains, before flagging. A raw SQL string inside a migration script is different from one inside a request handler.
- Dataflow sensitivity. Agents that track data flow from source to sink avoid flagging sanitized inputs. If user input passes through a validated serializer before reaching a query, the agent suppresses the finding.
- Feedback loops. When a developer dismisses a finding as a false positive, that signal is captured and used to refine the agent's behavior. Over time, agents learn the difference between a genuine vulnerability and a safe pattern specific to your codebase.
- Graduated rollout. New agents can run in "shadow mode", producing findings that are logged but not surfaced to developers until their precision meets a defined threshold.
What does the deployment workflow look like?
A practical deployment of custom detection agents at scale follows this sequence:
- Identify priority vulnerability classes. Start with the patterns that represent the highest risk in your codebase, not every CWE but the ones your threat model highlights.
- Define agent configurations. For each vulnerability class, specify the detection pattern, target languages/frameworks, severity, and remediation guidance.
- Integrate with CI/CD. Connect the agent orchestration layer to your source control platform so agents run automatically on every pull request.
- Run in shadow mode. Deploy new agents in observation mode for one to two sprint cycles. Measure precision and recall against manually reviewed findings.
- Tune and promote. Adjust thresholds, allowlists, and pattern definitions based on shadow mode data. Promote agents to active enforcement when precision meets your target, typically greater than 90%.
- Scale horizontally. Once the pipeline integration and orchestration layer are stable, adding new agents for additional vulnerability classes is incremental: define the configuration and deploy.
- Monitor and iterate. Track metrics per agent: findings per scan, false positive rate, mean time to remediation, developer override rate. Retire or retune agents that drift.
How does this differ from traditional SAST?
|
Dimension |
Traditional SAST |
Agent-based detection |
|
Rule format |
Language-specific query syntax (QL, YAML, regex) |
Natural language or structured policy plus AI reasoning |
|
Scope |
Full codebase scan |
Diff-scoped, PR-level analysis |
|
Remediation |
Separate workflow or absent |
Integrated per finding |
|
Customization |
Requires query language expertise |
Configurable by security engineers without parser knowledge |
|
Maintenance |
Manual rule updates per language |
Agents generalize across syntactic variations |
|
Feedback integration |
Limited or manual |
Automated feedback loops from developer actions |
Traditional SAST tools remain valuable for baseline coverage and compliance scanning. Agent-based detection targets organization-specific policies, framework-specific anti-patterns, and analysis that requires understanding code intent, not just code structure.
What should you look for in an agent-based detection platform?
When evaluating platforms or building internally, prioritize these capabilities:
- Detection and remediation are coupled. Every finding includes an actionable fix path. Detection-only tools create triage debt.
- Language and framework coverage is extensible. The platform should support adding new languages without rebuilding the analysis pipeline.
- Configuration is code. Agent definitions, tuning parameters, and policy mappings should be version-controlled and reviewable.
- Feedback is systematic. Developer actions on findings (accept, dismiss, modify) should feed back into agent tuning automatically.
- Execution is bounded. Agents should have defined resource limits and timeout behavior so they do not block CI/CD pipelines.
- Findings are deduplicated and prioritized. The orchestration layer should merge overlapping findings and surface the highest-risk issues first.
Amplify Security's code review engine implements this architecture pattern, with agents built to provide detection and remediation as a single unit across polyglot codebases. The design reflects the constraint that detection at scale is only useful if it produces findings developers can act on immediately, without a separate triage-and-fix workflow.
Summary
Scaling custom vulnerability detection across large codebases requires moving from monolithic rule sets to modular, AI-powered detection agents. Each agent owns a specific vulnerability pattern, runs in CI/CD on every code change, and pairs detection with remediation guidance. The architecture—pipeline integration, language-aware parsing, agent orchestration, and centralized configuration—enables security teams to add coverage incrementally without proportional engineering overhead. The key design principle is that detection and remediation must scale together, otherwise detection becomes noise.
Subscribe to Amplify Weekly Blog Roundup
Subscribe Here!
See What Experts Are Saying
BOOK A DEMO
Jeremiah Grossman
Founder | Investor | Advisor
Saeed Abu-Nimeh
CEO and Founder @ SecLytics
Kathy Wang
CISO | Investor | Advisor

Alex Lanstein
Chief Evangelist @ StrikeReadyFrequently
Asked Questions
What is vulnerability management, and why is it important?
Why is vulnerability management important?
What makes vulnerability management extremely challenging in today’s high-growth environment?
How can Amplify help me with vulnerability management?
What technology does the Amplify platform integrate with?
Have a
Questions?
Contact Us
Ready to
Get started?
Book A GUIDED DEMO
