

What Is Agentic AI Security: A Governance-First Definition for Enterprise Teams
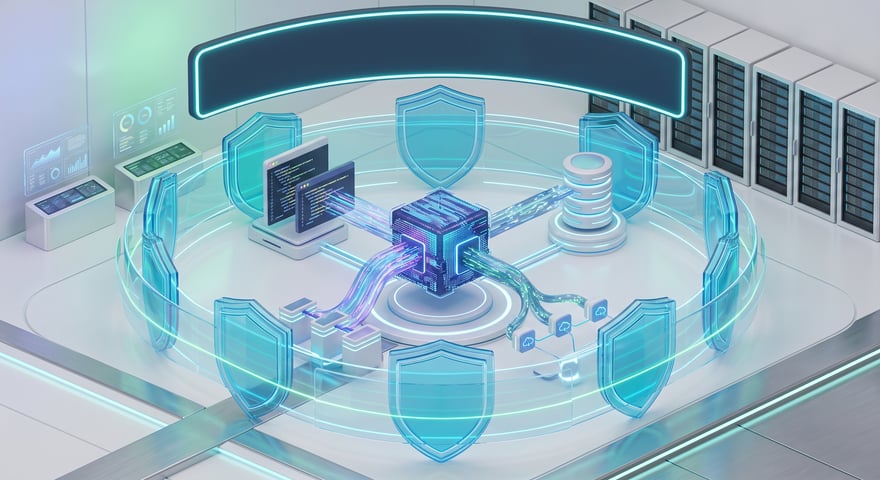
Generative AI fundamentally changed how enterprises process information. Agentic AI is changing how they execute tasks.
When a standard large language model receives a prompt, it returns text. It's passive. While a conventional generative system can still expose sensitive data or trigger downstream harm, the immediate impact is usually confined to the user's session and the data provided. An AI agent operates differently. These systems are designed to reason, make decisions, and interact with external environments. They can write code, commit to repositories, query production databases, and trigger external APIs without human intervention.
Once a model can take actions, the old security assumptions no longer hold. When an AI system acts on behalf of a user, the attack surface expands significantly. Security teams cannot rely solely on basic input filtering to protect their infrastructure. They need a framework designed for autonomous execution.
This article defines agentic AI security, explores the unique vulnerabilities these systems introduce, and outlines a governance-first approach, including what that governance actually looks like in a running production system.
The Shift from Passive AI to Active Agents
Generative models rely on user prompts to generate a response. The user remains the driver of the interaction. Agentic AI systems, by contrast, are goal-oriented: a user assigns an objective, and the agent determines the steps required to achieve it.
To accomplish this, agents are equipped with tools, essentially API integrations that let the model interact with the outside world. An enterprise agent might have access to Jira, GitHub, AWS environments, and internal Slack channels. It operates in a loop: observing its environment, planning a sequence of actions, using its tools to execute those actions, and evaluating the results before proceeding.
The moment you give a language model tools and autonomy, you transform it into an active participant in your network. The security risks shift from simple data exposure to infrastructure compromise. If an attacker can manipulate the decision-making process, that agent can become an attacker's path into systems if its permissions are too broad. Its effective reach is determined by the permissions the engineering team granted it, not by what it was originally intended to do.
Defining Agentic AI Security
Agentic AI security is the practice of implementing technical guardrails, identity controls, and governance frameworks to ensure autonomous AI systems operate predictably, securely, and within defined boundaries.
Traditional application security focuses heavily on deterministic software. A web application follows a specific logic path, and teams look for injection flaws, authentication bypasses, and known vulnerabilities in open-source libraries. SAST and DAST tools are highly effective at finding these deterministic flaws.
AI agents introduce a different kind of risk layer. They are non-deterministic, generating their own execution paths on the fly. SAST and DAST remain crucial for securing the underlying code of the application, but they fail to map the contextual risk of an AI making autonomous decisions. Agentic systems add tool-use, identity, authorization, and behavioral risks that standard scanning simply cannot predict.
Securing these systems requires a proactive stance. Governance in this context means establishing rigid boundaries around what an agent is allowed to do, rather than trying to predict every possible way it might fail. It requires shifting security left to the architecture phase: engineering leaders must dictate the identity of the agent, the scope of its access, and the human oversight required for critical actions before deployment, not after.
Core Security Risks in Enterprise AI Agents
Autonomous privilege escalation. Developers often grant AI agents broad permissions to ensure they function smoothly, for example an agent designed to help debug code might get read and write access to multiple repositories. If that agent operates under a single, highly privileged service account, it becomes a prime target. An attacker interacting with the agent could manipulate it into taking actions outside its intended scope, and because the agent possesses the necessary credentials, the underlying systems will execute the commands, assuming they're legitimate. The AI ends up acting as a proxy for the attacker.
Data exfiltration via API abuse. Agents routinely interact with sensitive data to complete their tasks. An HR agent might have access to employee records to answer policy questions. If an attacker compromises the agent's instructions, they can instruct it to package sensitive data and send it to an external server via an available API or outbound webhook. The danger is that the exfiltration looks like normal agent activity, and conventional DLP solutions may struggle to distinguish a legitimate agent operation from a malicious exfiltration event.
Indirect prompt injection and execution. Direct prompt injection happens when a user types a malicious command directly into a chat interface. Indirect injection is more dangerous for agentic systems: the malicious instructions are hidden in data the agent is expected to process, for example inside a seemingly harmless text file or a website the agent is tasked with summarizing. When the agent reads the file, it processes the hidden instructions as a system command, and if it has execution capabilities, it carries out the attacker's hidden instructions automatically.
Building a Governance Framework for Agentic AI
To safely deploy autonomous workflows, enterprises must move beyond point-in-time security assessments. A governance framework provides the structural rules required to contain these systems.
Identity and access management for agents. Organizations must treat AI agents as non-human identities requiring strict IAM controls. An agent should never operate under the context of a human user's account. It must have its own service account with clearly defined, least-privilege permissions, and access should be contextual: if an agent is tasked with reading a database to generate a report, it should only have read access for the duration of that specific task. Just-in-time access provisioning ensures agents don't maintain standing privileges that can be exploited.
Establishing the blast radius. Engineering teams should assume that an agent might eventually be compromised or make a catastrophic error, and the architecture must limit the damage when that happens. This means network segmentation, strict API rate limiting, and a human-in-the-loop requirement for destructive actions. An agent should never be permitted to drop a production database or modify core IAM policies without explicit approval from an authorized human operator.
Continuous monitoring and automated remediation. Because agents are non-deterministic, point-in-time scanning is insufficient. Teams need continuous monitoring of the agent's behavior in production: analyzing tool usage, tracking API calls, and watching for deviations from established baselines. When anomalous behavior is detected, automated remediation should take over, revoking the agent's API keys, isolating it from the network, and alerting the security operations center before an agent causes material damage.
What This Looks Like in Practice: A Governance Model Walkthrough
The framework above is easier to trust once you see it applied to an actual production question: who is governing the agent, specifically, at the moment it acts?
Finding vulnerabilities at scale isn't the hard part anymore. Trusting what an agent does next is. A security team can tolerate a scanner that produces false positives, because a human reviews the list before anything ships. An agent that opens pull requests and proposes merges is a different category of risk. If it's wrong even a small percentage of the time, and it's running across hundreds of repositories, the blast radius of being wrong grows with adoption instead of shrinking. This is why Amplify Console is built around a simple rule: an agent should get more room to act only when its output is easy to verify. Detection agents can earn a wider mandate because their output, a flagged vulnerability, is inherently reviewable. Remediation agents need a narrower one, because their output is a code change landing in a pull request, where a developer still has to approve it before it merges.
That principle plays out as three layers of control:
Reachability before action. Before any custom detection agent acts on a finding, Amplify's reachability engine determines whether the flagged vulnerability is actually callable in the application's real execution paths. A critical CVE sitting in a dependency the application never imports isn't treated as an actionable finding. That's a decision about authority, not just accuracy: it keeps agents from generating noise a security team then has to govern manually, and it means the agent's authority to act is gated by evidence of exploitability, not a vendor's generic severity score. Concretely: a dependency scanner flags a critical library issue in a payment service. Before anything happens, the harness checks whether the vulnerable function is actually called anywhere in the service's code paths. If it's called in a checkout flow handling user input directly, the reachability engine confirms exploitability, a scoped detection agent picks it up, and only then does an auto-fix engine draft a repository-specific patch. If the same library were sitting unused in dead code, the finding gets logged but never escalated to a fix.
Scoped, custom detection agents. Generic AI agents pointed at a codebase without context tend to apply generic rules. The alternative: security engineers define the priorities, standards, and architectural constraints a custom detection agent operates within before it's deployed. That scoping step is itself a governance control. An agent built to detect a specific class of authentication flaw in a specific service is easier to audit, easier to reason about, and easier to shut off if it misbehaves than a single general-purpose agent given open-ended authority across the entire environment.
Human review at the point of merge. An auto-fix engine can generate a deployment-ready patch, but that patch arrives as a pull request in the existing repository, whether GitHub or GitLab, and nothing merges without a developer reviewing it the same way they'd review a colleague's contribution. The agent proposes. It does not merge itself. That's what keeps the system running on a governance model security teams already know, code review, rather than an entirely new trust model adopted overnight.
What happens when the agent is wrong. No serious vendor should claim their agents are never wrong. What matters operationally is what happens after an agent produces a bad fix or a false positive. Because remediation happens inside the normal review workflow, a wrong fix gets caught the same way a wrong human commit gets caught: through review, tests, and CI. Because detection agents are scoped narrowly, a misbehaving agent's impact is contained to the class of finding it was built to detect, not the entire codebase. And because the reachability engine gates action on exploitability evidence, the volume of low-value findings an agent could act on incorrectly is already reduced before it becomes a review problem at all. This is also why audit trails and narrative reporting matter: when a security leader has to explain to a CTO or board why remediation velocity moved the way it did, they need a record of what agents did, why they acted, and what evidence supported the action, not just a list of closed tickets.
Governance is not the same as slowness. There's a temptation to assume governance means adding friction back into a process that agentic AI was supposed to remove. It doesn't have to. Reachability checks, scoped agents, and a review checkpoint aren't extra steps bolted onto the workflow, they are the workflow. Developers still merge through the same process they always have. Security engineers still own detection priorities. What changes is that the manual labor of triage, correlation, and first-draft remediation moves to the agent layer, while the decision rights over what counts as a risk and what gets merged stay with people.
Scaling this looks like adding more scoped agents, each producing findings that have already passed a reachability check and generating fixes that land in a queue developers already use, not loosening the boundaries around any single agent.
Frequently Asked Questions
What is the difference between generative AI and agentic AI? Generative AI creates content based on user prompts. Agentic AI executes tasks autonomously by interacting with external systems, APIs, and databases to achieve a specific goal.
Why is prompt injection more dangerous for AI agents? In standard generative AI, prompt injection usually results in bad text output. In agentic systems, it can lead to unauthorized code execution, data deletion, or system compromise, because the agent has the tools to take action on what it was tricked into believing.
How do you apply zero trust to AI agents? By assigning unique identities to AI agents, enforcing least privilege, requiring continuous authentication for API calls, and never inherently trusting the output or execution path of the model just because it came from an internal system.
Does allowing an agent to open pull requests mean it can merge code without review? No, not in a properly governed system. The agent generates a patch and submits it as a pull request. A developer reviews and approves it the same way they'd review any other contribution before it merges.
How does governance prevent agents from acting on irrelevant vulnerabilities? A reachability engine checks whether a flagged vulnerability is actually callable in the application's real execution paths before it's treated as actionable, filtering out theoretical findings that aren't exploitable in that specific environment.
Can security engineers control what a detection agent is allowed to look for? Yes. Custom detection agents should be scoped by the security team to specific priorities and architectural standards before deployment, rather than applying generic, one-size-fits-all rules across the whole codebase.
Securing the Autonomous Enterprise
Agentic AI will drive the next wave of enterprise productivity. It will also introduce an entirely new category of security threats. Organizations that treat AI agents like standard software deployments will face severe challenges.
Agentic AI security does not scale by giving agents more authority. It scales by giving them narrower, better-evidenced authority and keeping the decision points, what to fix and what to merge, with the humans who are accountable for the outcome. Security leaders need this governance in place before agents reach production, not retrofitted after an incident.
Ready to see how enterprise teams govern, monitor, and secure agentic AI deployments? Request a technical demo today.
Subscribe to Amplify Weekly Blog Roundup
Subscribe Here!
See What Experts Are Saying
BOOK A DEMO
Jeremiah Grossman
Founder | Investor | Advisor
Saeed Abu-Nimeh
CEO and Founder @ SecLytics
Kathy Wang
CISO | Investor | Advisor

Alex Lanstein
Chief Evangelist @ StrikeReadyFrequently
Asked Questions
What is vulnerability management, and why is it important?
Why is vulnerability management important?
What makes vulnerability management extremely challenging in today’s high-growth environment?
How can Amplify help me with vulnerability management?
What technology does the Amplify platform integrate with?
Have a
Questions?
Contact Us
Ready to
Get started?
Book A GUIDED DEMO
